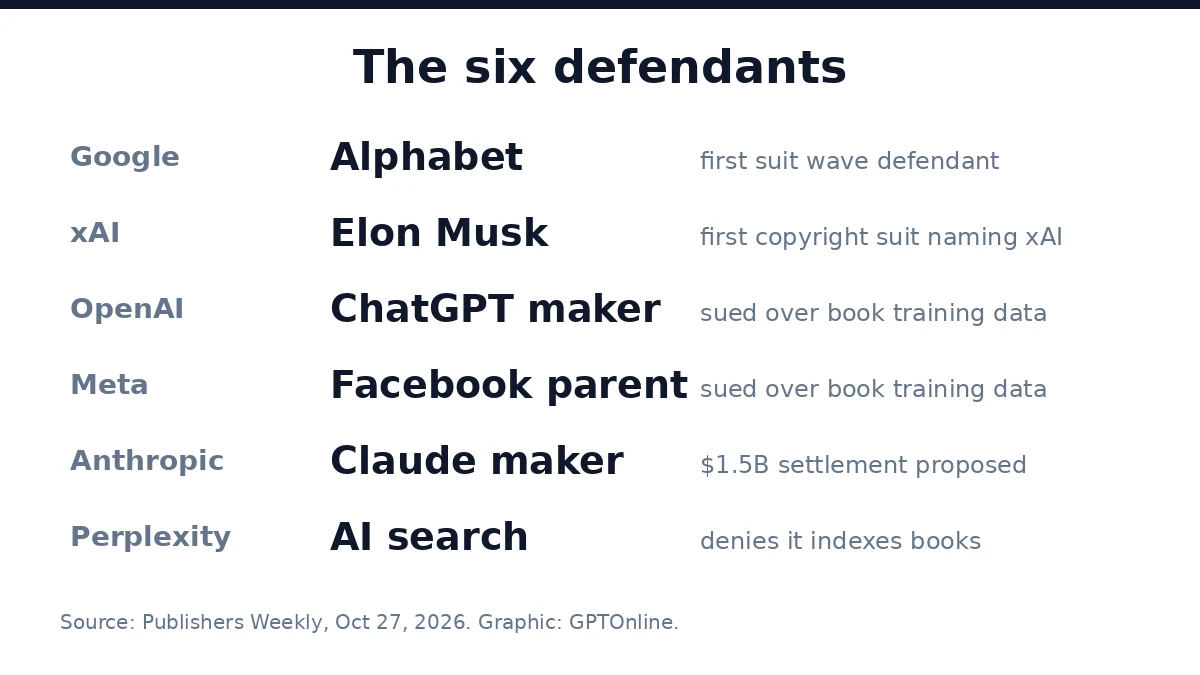
Six authors have sued six of the biggest names in artificial intelligence in a single federal lawsuit, accusing Google, xAI, OpenAI, Meta, Anthropic and Perplexity of building their chatbots on pirated books. The complaint, filed Monday in the Northern District of California, says the companies copied the authors’ works from pirate libraries without permission, licensing or compensation.
The lead plaintiff is John Carreyrou, the two-time Pulitzer Prize winning New York Times reporter whose book Bad Blood exposed the Theranos fraud. He is joined by Lisa Barretta, Philip Shishkin, Jane Adams, Matthew Sack and Michael Kochin. It is the first copyright lawsuit to name Elon Musk’s xAI as a defendant.
What the Lawsuit Alleges
According to the complaint, the companies took copies of the authors’ books from well known pirate libraries, including LibGen, Z-Library and OceanofPDF, and fed them into the large language models that power their chatbots. The authors argue that high quality books are the “gold standard” of training data and that the companies “used those copies to build systems now worth many hundreds of billions of dollars.”
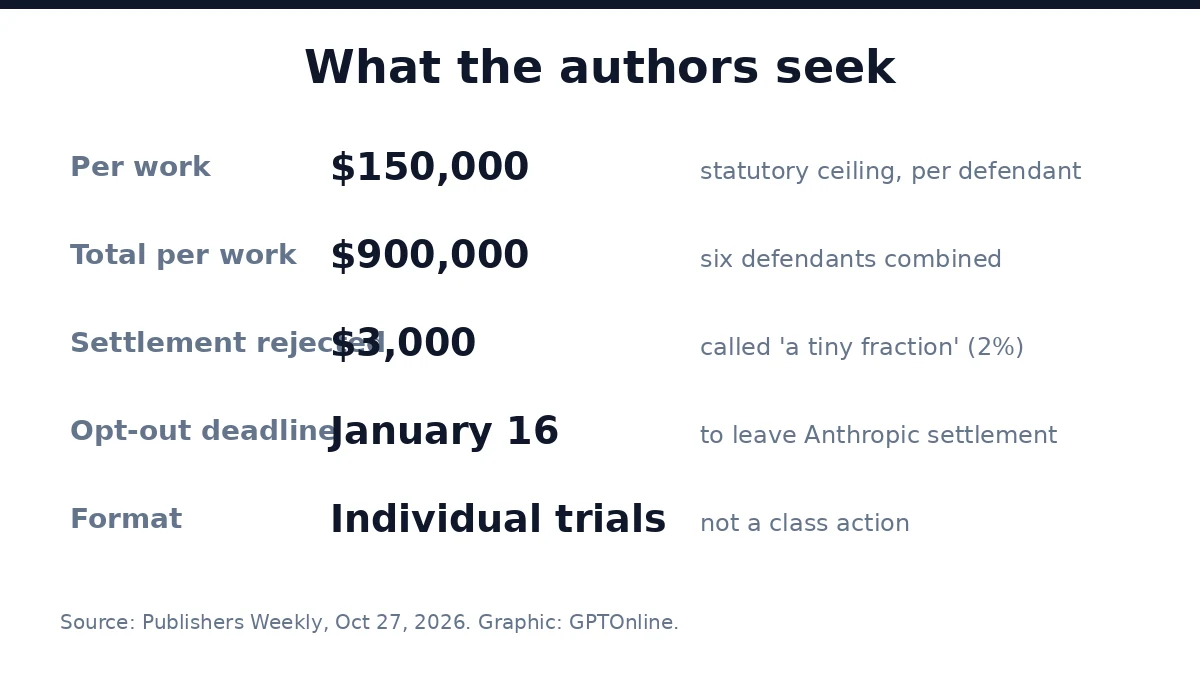
The case is not a class action. Each author is seeking an individual jury trial over their own work, a strategy the plaintiffs’ attorneys say keeps their rights from being diluted in a sprawling settlement. The filing is collective, but the relief sought is individual.
Why the Authors Opted Out
The six authors are among those who opted out of the proposed $1.5 billion settlement of the lawsuit against Anthropic, announced in September. Under that deal, authors and publishers would receive $3,000 each. The new filing calls that sum “a tiny fraction (just 2%) of the Copyright Act’s statutory ceiling of $150,000 in addition to attorneys’ fees per willfully infringed work.”
Instead, the plaintiffs are seeking the full statutory amount: $150,000 for each work against each defendant, or $900,000 in total per work. Authors have until January 16 to opt out of the proposed Anthropic settlement.
The backdrop is a ruling by Judge William Alsup, who presided over the Anthropic case. Alsup found that training AI models on books can be fair use, but held that the use of pirated copies demanded a remedy, which led to the proposed settlement. The new lawsuits lean on that distinction, arguing that the piracy, not the training alone, is the violation.
How the Companies Responded
Perplexity denied the claim. Jesse Dwyer, the company’s head of communications, told Bloomberg that Perplexity does not index books. xAI responded to Bloomberg with an email reading “Legacy Media Lies.” Spokespeople for the other defendants did not immediately respond to requests for comment.
As of Tuesday afternoon, no date had been set for a preliminary court hearing.
Why It Matters
The lawsuit lands at a moment when the legal rules for AI training data are still being written case by case. A win for the authors on the pirated copies argument would put a price on the libraries many labs relied on in their early training runs, and it would give individual creators a path to damages far larger than the class settlement on offer.
It also widens the circle of defendants. By naming xAI for the first time, and by suing six companies together rather than one at a time, the authors are testing whether the industry’s training practices can be challenged as a shared pattern rather than a series of isolated disputes. The answer will shape how labs source books, and what they pay for them, for years.
Sources
- Publishers Weekly: Authors File New Lawsuit Against AI Companies Seeking More Money
- The Economic Times: New York Times reporter sues Google, xAI, OpenAI over chatbot training
- Webull: Elon Musk’s xAI, Meta And Google Sued By New York Times Reporter John Carreyrou Over Alleged Use Of Pirated Books To Train AI