Together AI has launched Together Compiler, a system that uses teams of AI agents to rewrite the GPU code behind the models it serves, so new open-source models get faster overnight instead of over weeks. The company calls it the first step toward recursive self-improving inference, and it is already running across many of its most popular serverless endpoints.
The announcement, made via Business Wire on November 4, 2026, frames the compiler as the first project of a larger initiative Together AI calls Polymorphic Inference: serving infrastructure that continuously retunes itself as models, traffic and hardware change.
What Was Announced?
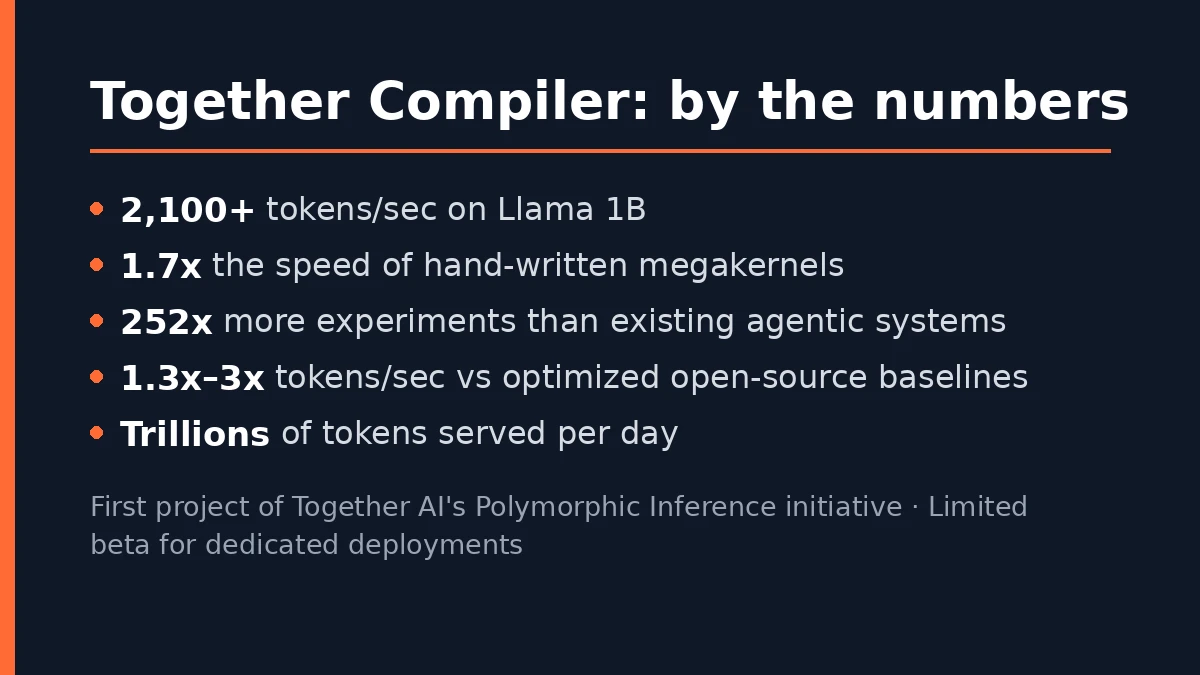
Together Compiler takes the traffic shape, model and hardware as inputs, then uses agents to generate and measure candidate optimizations for the inference engine. Its design maximizes agent iteration velocity, running 252x more experiments than existing systems that use agents for inference optimization, keeping costly GPUs fully utilized.
On Llama 1B, Together Compiler reached over 2,100 tokens per second and up to 1.7x the speed of hand-written megakernels, including Together AI’s own. Across tests on Kimi K3, GLM 5.3, MiniMax M3.1-Flash and DeepSeek v4.1-Flash, the compiler delivered 1.3x to 3x the tokens per second of highly optimized open-source baselines in under 24 hours.
Key Features and Details
The company describes Together Compiler as “the first step towards recursive self-improving inference.” The technical paper says winning candidates undergo verification tests for KV-cache contamination and output quality before they can be served, and the launch post reports startup comparison figures of 467 seconds to serving for the status-quo sequence versus 9.0 seconds with Together Compiler’s setup.
Together Compiler is running today across many of Together AI’s most popular serverless endpoints, and the company says it serves trillions of tokens per day. Customers can join a limited beta to use it on their own dedicated deployments, with self-serve access coming soon. A research paper is available at together.ai/together-compiler-paper.
Why It Matters
Inference optimization has traditionally been expert hand work: engineers spend weeks writing and tuning GPU kernels for each new model. Together AI’s bet is that agents can do it better and continuously, adapting to faster model releases, diverse architectures and changing traffic shapes without human intervention.
If the vendor-reported numbers hold up under independent evaluation, the approach could compress a weeks-long tuning cycle into an overnight run, lowering serving costs across the open-model ecosystem. As open-weight models release faster than ever, infrastructure that retunes itself may matter as much as the models themselves.
Sources
- Business Wire: Together AI Launches Together Compiler for Continual Optimization of Open Source AI Models (official announcement, November 4, 2026)
- Unite.AI: Together AI Brings Continuous Compilation to Production Inference
- Morningstar: Together AI Launches Together Compiler (Business Wire release)