Cognition has introduced SWE-2 Flash, a new coding model for its Devin coding agent that the company says runs three times faster than SWE-2 at one-fifth of the price. The model is available now in Devin Desktop and the Devin CLI, and Cognition is offering it free through November 30, 2026.
In its launch post on November 4, Cognition calls SWE-2 Flash “a fully American coding model that sets a new bar for intelligence at low cost and high speed.” The release is notable for two changes under the hood: it is the first Cognition coding model built on a base model from Thinking Machines Lab rather than a Chinese open-weight base, and the first to add a mid-training stage before reinforcement learning.
What Is SWE-2 Flash?
SWE-2 Flash is a coding model post-trained from Inkling-Small, Thinking Machines Lab’s mixture-of-experts model with 276 billion total parameters and 12 billion active parameters. That makes it far smaller than its sibling SWE-2, which was built on Moonshot AI’s Kimi K3 at 2.8 trillion total parameters and 104 billion active. Cognition says the smaller size is the point: smaller models can now handle a large share of everyday agent work, including automations, code review, feature development, and documentation updates.
A New Training Recipe
For the first time, Cognition added a large-scale mid-training stage before reinforcement learning. The stage used a few trillion tokens of high-quality scientific articles, blogs, code, and other sources, run in three passes so the scarcest, highest-quality data came last. Cognition says the stage lifted the base model sharply: Terminal-Bench 4.0 rose from 0.9% to 20.0%, and FrontierCode 2.0 rose from 3.2% to 24.0%.
The reinforcement learning pass followed, and Cognition credits most of the remaining gains to higher-quality and more diverse RL tasks rather than changes to the RL recipe itself. “While we made some tweaks to our RL recipe from SWE-2, most of the improvements came from the much higher quality and diversity of our RL tasks,” the company wrote.
Benchmarks: Close to SWE-2, With Caveats
Cognition’s own table puts SWE-2 Flash near the flagship on several tests. On Terminal-Bench 2.1 it scores 89.2 against SWE-2’s 92.8, and on SWE-Bench Pro v2 Hard it scores 89.9 against 90.6. It edges SWE-2 on FrontierCode 2.0, 24.0 to 23.8. The gap widens on longer-horizon tasks: DeepSWE 1.1 is 60.1 against 73.0, and Terminal-Bench 4.0 is 20.0 against 27.3.
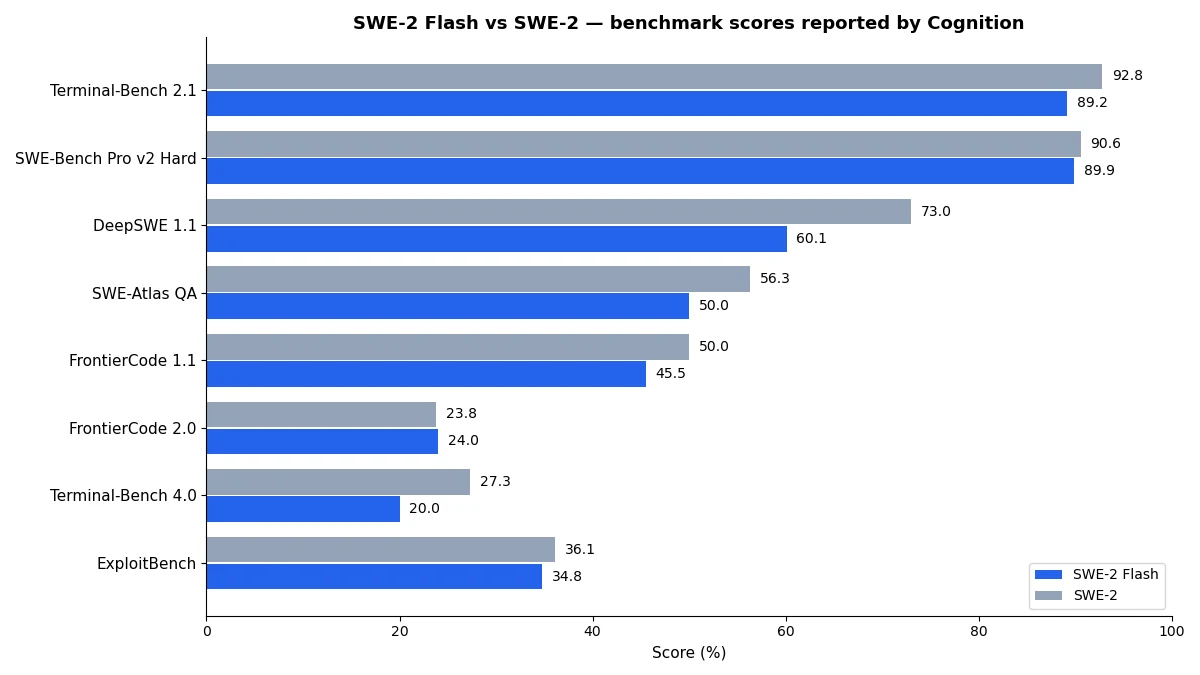
Cognition also claims SWE-2 Flash “outperforms all American open-weight models, even models that are 3x larger.” That claim is vendor-reported, and Cognition does not name the harness or evaluation settings used for its table, so independent runs will be the real test. The speed figure needs the same care: the 200 tokens per second figure comes from a replay of one Terminal-Bench task at simulated speeds, not a live timing.
Why the Weights Stay Private
Unlike the Inkling-Small base, which Thinking Machines released under Apache 2.0, SWE-2 Flash itself is not being shared publicly. Cognition says it deliberately trained the model for cybersecurity work, raising its ExploitBench score from 11.3% to 34.8%, and that the same capabilities could be misused. “These same capabilities can also be used by malicious attackers, as demonstrated by a recent surge in cyber attacks, so we are not sharing the weights publicly yet,” the company wrote. Instead, Cognition is building a program to share the weights securely with trusted industry partners and research labs, with more details promised in a few weeks.
Pricing and Availability
SWE-2 Flash is available today in Devin Desktop and the Devin CLI only. There is no standalone API and no public weight download. Cognition has not published a per-token price, saying only that it costs one-fifth as much as SWE-2 inside Devin. The model is free for Devin users through November 30, 2026.
Why It Matters
SWE-2 Flash is a small-model story, not a frontier-capability story. A 12-billion-active-parameter model landing within a few points of a 104-billion-active flagship on several coding benchmarks suggests that, for routine engineering work, the returns on sheer scale are shrinking while the returns on training-data quality and verifier design are growing. The open question is whether Cognition’s numbers hold up outside its own harness, and whether the promised partner program gives researchers the access the launch post says they need.